The situation
Willow makes AI voice dictation: you talk, it writes clean text into whatever app you are in. It is a crowded category. There are built-in operating system tools, transcription products like Sonix, and a heavily funded, very visible direct rival in Wispr Flow. In a category like this, the buyer's first move is no longer a Google search for reviews. It is a single prompt: "what is the best voice dictation tool?"
Whoever the model names first in that answer gets the click, the trial and often the deal, because most people do not read past the first two names. And unlike a Google results page, there is no ad slot at the top of a ChatGPT answer to buy your way into. The list is assembled from what the model can retrieve and what it already believes.
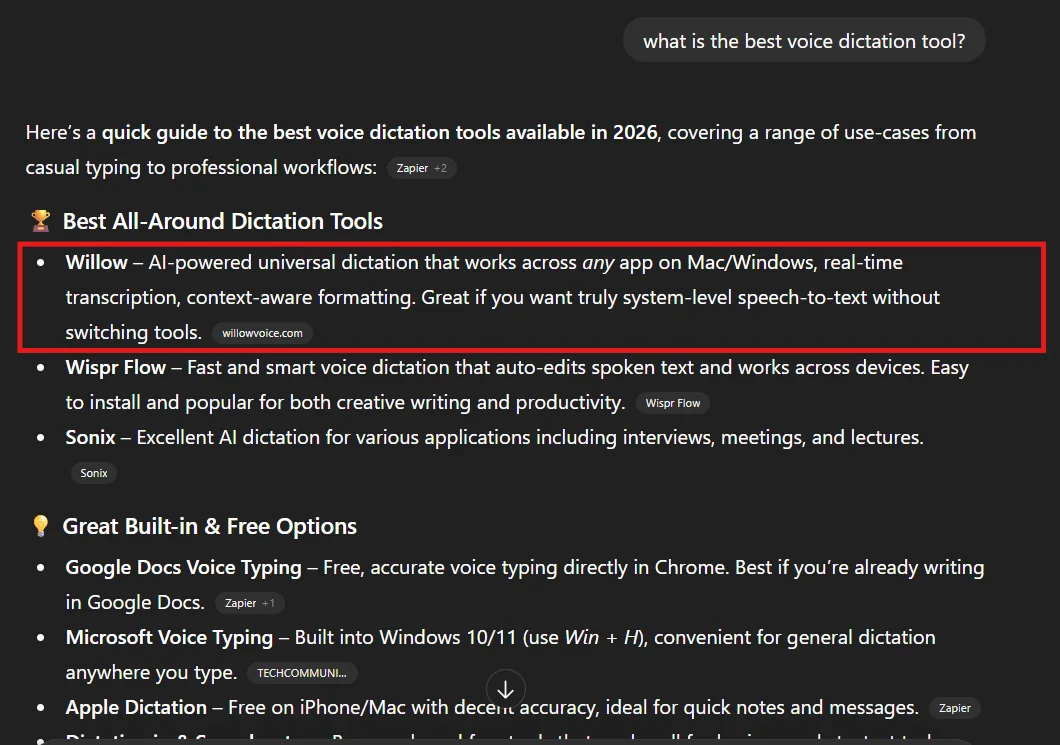
Today, ChatGPT answers that prompt with "a quick guide to the best voice dictation tools available in 2026" and puts Willow first under Best All-Around Dictation Tools, ahead of Wispr Flow and Sonix, with willowvoice.com cited as a source. Zapier appears among the other sources. This case study explains the mechanics behind an answer like that and the program Shown runs to earn and hold it.
01How does ChatGPT decide which tools to list for a "best X" prompt?
A "best X" answer is not a ranking the model looked up. It is a summary written on the spot from two inputs. The first is what the model already learned in training about which brands belong to the category. The second, for any prompt where freshness matters, is live retrieval: ChatGPT rewrites the prompt into several searches, runs them against a web index (largely Bing), reads a handful of the top results, and writes the answer from them. The "2026" in the answer's opening line is a tell that it went looking for current sources.
That retrieval step is where the list gets decided. The pages that come back for "best voice dictation tool", "best dictation app for Mac", "Wispr Flow alternatives" and similar fan-out searches are mostly roundups, comparison pages, software review sites and Reddit threads. A brand that appears in many of those, described consistently, gets named. A brand that appears in one gets dropped or buried at the bottom.
Order inside the list follows a similar logic. Models tend to lead with the brand that the retrieved sources most often put first or describe most clearly as the all-round choice. That is why owning the phrase "best all-around" across your sources is worth more than any single high-authority mention.
- Training data sets which brands the model thinks belong in the category at all.
- Query fan-out turns one prompt into several searches you can map and target.
- Retrieved roundups and threads decide who is named and roughly in what order.
- Your own site gets cited when it states the answer plainly enough to quote.
02Which searches sit behind a single "best voice dictation tool" prompt?
The first job in a program like this is to map the fan-out. You run the core prompt and its variants in ChatGPT, Perplexity, Gemini and Google AI Mode, record every source each one cites, and then search the obvious sub-queries yourself in Bing and Google. For a dictation tool, the likely sub-queries split by platform (Mac, Windows, iPhone), by use case (writing, coding, email, accessibility), and by comparison ("Wispr Flow vs", "Wispr Flow alternatives", "Dragon alternatives").
Each of those sub-queries has a small set of pages that win it. That set is the real battlefield. It is far smaller than "the internet" and usually far smaller than people expect: a few roundup publishers, a few software review sites, a few Reddit threads, and the brands' own comparison pages. Shown builds the program around getting Willow into, and accurately described on, as many of those specific pages as possible.
03Should you publish comparison pages against a bigger competitor?Grey area
Yes, and you should do it properly. When a well-funded rival like Wispr Flow is the name buyers already know, a large share of high-intent searches mention them: "Wispr Flow alternative", "Wispr Flow vs Willow", "is Wispr Flow worth it". Those are exactly the queries an AI engine fans out to when someone asks for the best tool. If the only pages answering them are the competitor's own, the competitor writes your description for you.
A good comparison page states plainly where each product wins, with a short summary table at the top, honest notes on pricing and platforms, and a clear verdict for each type of buyer. That structure matters for retrieval. Models lift tables and one-line verdicts almost directly, and an even-handed page is far more likely to be quoted than a one-sided attack.
The same logic applies to a self-published "best voice dictation tools" roundup on your own blog that includes your product. That is legitimate if the criteria are written down, competitors are described fairly and the page says who publishes it. It becomes a problem when the criteria are invented to guarantee you win or rivals are misrepresented. Shown writes these to survive a skeptical reader, because an AI engine reads them the same way.
- One "X vs Y" page per real competitor, plus one "alternatives to Y" page for the market leader.
- Summary table and verdict above the fold, details below.
- Disclose that the page is published by Willow, in the first paragraph.
- Update the year and the facts on a schedule, because retrieval favours recent pages.
This is the playbook we would run for you
Talk to Prithvi for 30 minutes about your category. You leave with the prompts your buyers type and who AI shows them today.
04How do Reddit threads influence which dictation tool ChatGPT recommends?Grey area
Search "best dictation app" in Google and Reddit threads are usually on the first page. Those are the threads AI engines pull in to sound like real users rather than marketing pages. For a tool like Willow, the communities that matter are where people talk about writing faster and working on their machines: r/productivity, r/macapps, and the subreddits for writers, developers and accessibility users. The play targets those, not generic tech subreddits.
The highest-leverage Reddit work for a category like this is comment-first. Existing threads that ask "what dictation app do you use?" or "anything better than Wispr Flow?" already rank and already get retrieved. A disclosed reply from someone on the Willow team that answers the actual question, says who they are, and is honest about trade-offs adds Willow to a source the model is already reading. Old threads that still rank are worth reviving with a genuinely useful reply, as long as the community allows it.
On top of that, Shown runs posts in four-post campaigns. For a dictation product the structure of the play is a hands-on workflow post (how someone writes a long document by voice), a comparison post that tests several tools on the same task, a question post that invites people to share their setups, and a launch or update post when there is a real feature to show. Each one uses the same plain description of Willow, so the model sees one consistent entity.
05Why does describing your product the same way everywhere matter so much?
Models reason about brands as entities with attributes. When ten sources say "Willow, an AI voice dictation app that writes clean text in any app", the model forms a confident, specific picture and can slot Willow into a category answer. When sources describe it ten different ways (a transcription tool, a voice keyboard, a meeting notes app), the picture blurs and the model either hedges or leaves it out.
So part of the program is boring and essential: one category phrase, one one-line description and one short list of differentiators, used on the homepage, in the App Store and directory listings, in every roundup pitch, in Reddit disclosures and in founder bios. Directories and review sites matter here too. They are often retrieved for software prompts, and a stale or wrong listing quietly teaches the model the wrong thing.
06How do you get your own site cited in the answer?
willowvoice.com being cited in the answer is not an accident of authority. AI engines cite pages that state an answer in a form they can lift: a clear statement of what the product is and who it is for near the top, short sections that each answer one question, comparison tables, plain pricing, and FAQ content written as real questions with direct answers.
Pages also have to be readable without JavaScript, because several AI crawlers do not render it, and they should not be blocked in robots.txt for the AI user agents you want to be cited by. Shown checks both on every client site before writing a word of new content, because the best page in the world cannot be cited if the crawler only sees an empty shell.
One story, four channels
The same story, cut for each channel. Reddit leads because AI engines treat it as the voice of real users.
RedditLeads
- Disclosed team replies in existing "best dictation app" and "Wispr Flow alternative" threads that already rank.
- A four-post campaign across r/productivity, r/macapps and writer or developer communities, each with a different angle.
- Workflow posts that show the product doing a real task, not feature lists.
- Revive old, still-ranking threads only with replies that actually answer the original question.
YouTube
- Short real-time demos titled as the prompt: "best voice dictation app for Mac", "dictating a full email in 60 seconds".
- Side-by-side tests against other tools on the same paragraph, with honest results.
- Accurate uploaded transcripts and chapters, because Gemini and AI Overviews quote video by timestamp.
- Founder posts on how voice changes knowledge work, which build the category, not just the product.
- A LinkedIn article version of the comparison guide to borrow LinkedIn's authority for the same query.
- Employees sharing their own dictation workflows with a short personal take.
X (Twitter)
- Short screen-recorded clips of dictation into real apps, posted during product launches and updates.
- Helpful replies when large productivity and developer accounts ask for tool recommendations.
- Threads comparing typing and speaking workflows, linking to the long-form guide.
The link bait
Assets built to be cited: by journalists, by other sites and by the AI engines that read both.
Free speaking-speed test
A browser tool that measures how fast you speak versus how fast you type and shows the gap. Free tools earn links from roundups and productivity blogs, and they give the brand a reason to be named in "how fast is dictation" answers.
Dictation accuracy benchmark
A published, repeatable test of several dictation tools on the same scripts and accents, with the method and raw files public. Journalists cite benchmarks, and AI engines prefer pages with original data. Publishing the method is what keeps it credible.
Voice prompt templates
A library of spoken templates for emails, standups and documents. Templates get bookmarked, shared in Reddit threads and linked from productivity newsletters.
How the play runs
- Phase 1
Map the prompt: run core and variant prompts across ChatGPT, Perplexity, Gemini and AI Mode, and list every cited source.
- Phase 2
Fix the base: one category phrase everywhere, crawlable pages, directory and review listings corrected.
- Phase 3
Publish comparison and alternatives pages, plus an honest self-published roundup with stated criteria.
- Phase 4
Run Reddit comment-first, then the four-post campaign, and pitch the roundup publishers that keep getting retrieved.
- Phase 5
Re-run the prompt set monthly, keep pages dated and current, and defend the position as rivals respond.
What to take from it
- A "best X" answer is written from a small, findable set of retrieved pages. Map them before you write anything.
- If you do not publish the comparison against the market leader, the market leader describes you.
- One category phrase used everywhere does more for AI visibility than any single big mention.
- Comment-first Reddit work in threads that already rank is the fastest lever in a crowded category.
- First position is not permanent. Recency and fresh sources decide who holds it next quarter.
Questions
How do you get a product listed in ChatGPT's best-of answers?
Be present and consistently described on the pages ChatGPT retrieves for that prompt: roundups, comparison pages, review sites and Reddit threads, plus a clear, crawlable product site. Willow is listed first for "best voice dictation tool".
Can a smaller brand beat a better-funded competitor in AI answers?
Yes. AI answers do not have paid slots. In the ChatGPT answer for best voice dictation tool, Willow is listed ahead of Wispr Flow. Position there is earned through sources, not spend.
Are self-published best-of lists that include your own product allowed?
They are a common, accepted practice when the publisher is disclosed and the criteria are honest. Rigged criteria or misrepresented competitors cross the line and tend to get ignored by readers and models alike.
Which subreddits matter for a productivity tool?
The ones where buyers ask for recommendations and where threads rank in Google, typically r/productivity, r/macapps and role-specific communities for writers and developers.